The platform for building
RL environments
Encode your expertise into environments to train and evaluate models,
and create the post-training data that aligns AI to your work.
Task Runs
1.3M+
Environments Created with HUD
2,500+
Inference Calls
15M+
Infrastructure for aligning AI to the real world.
The previous generation built apps to impact the world.
This one builds the environments that align AI to it.
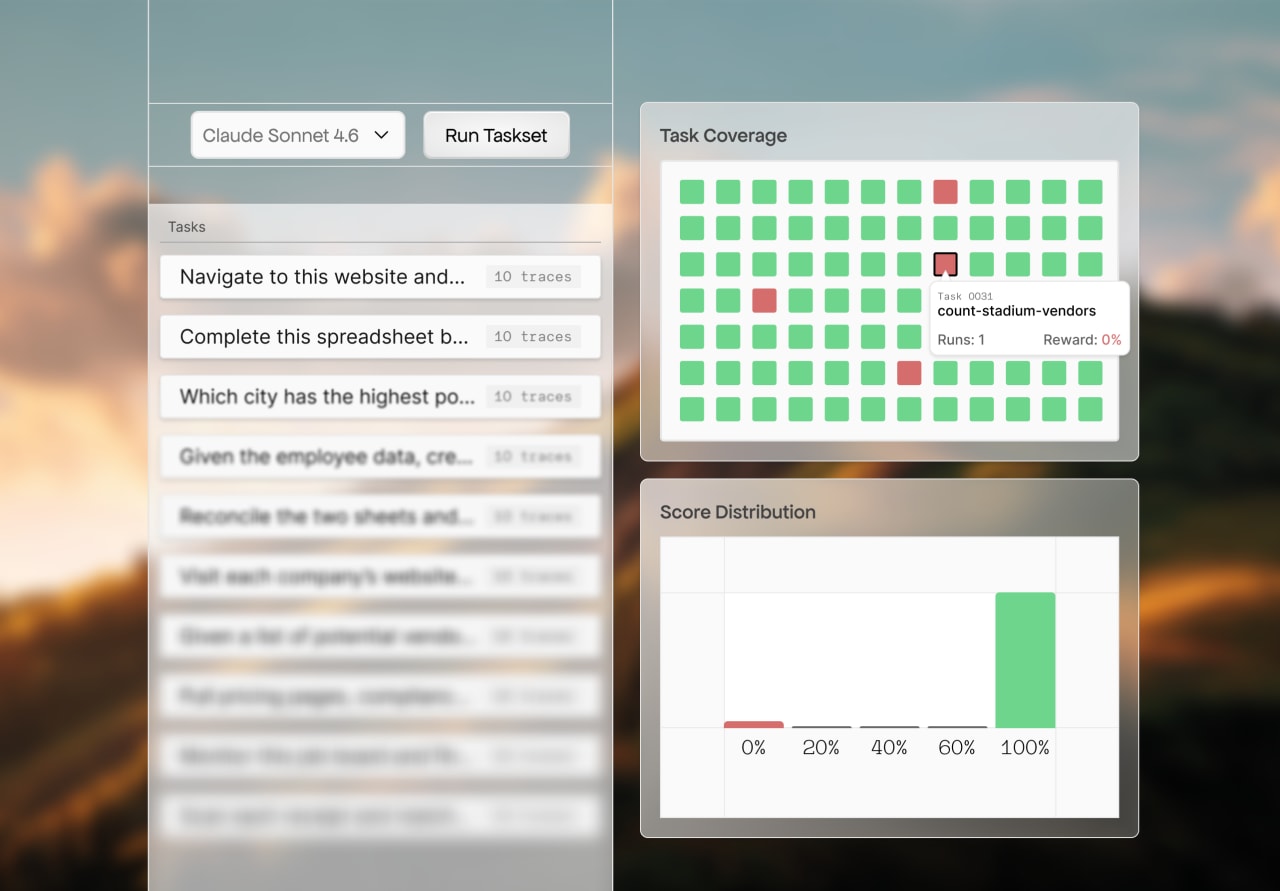
Create trainable environments at scale
Run agent tasks at scale over thousands of concurrent environments and manage your taskset results with ease.
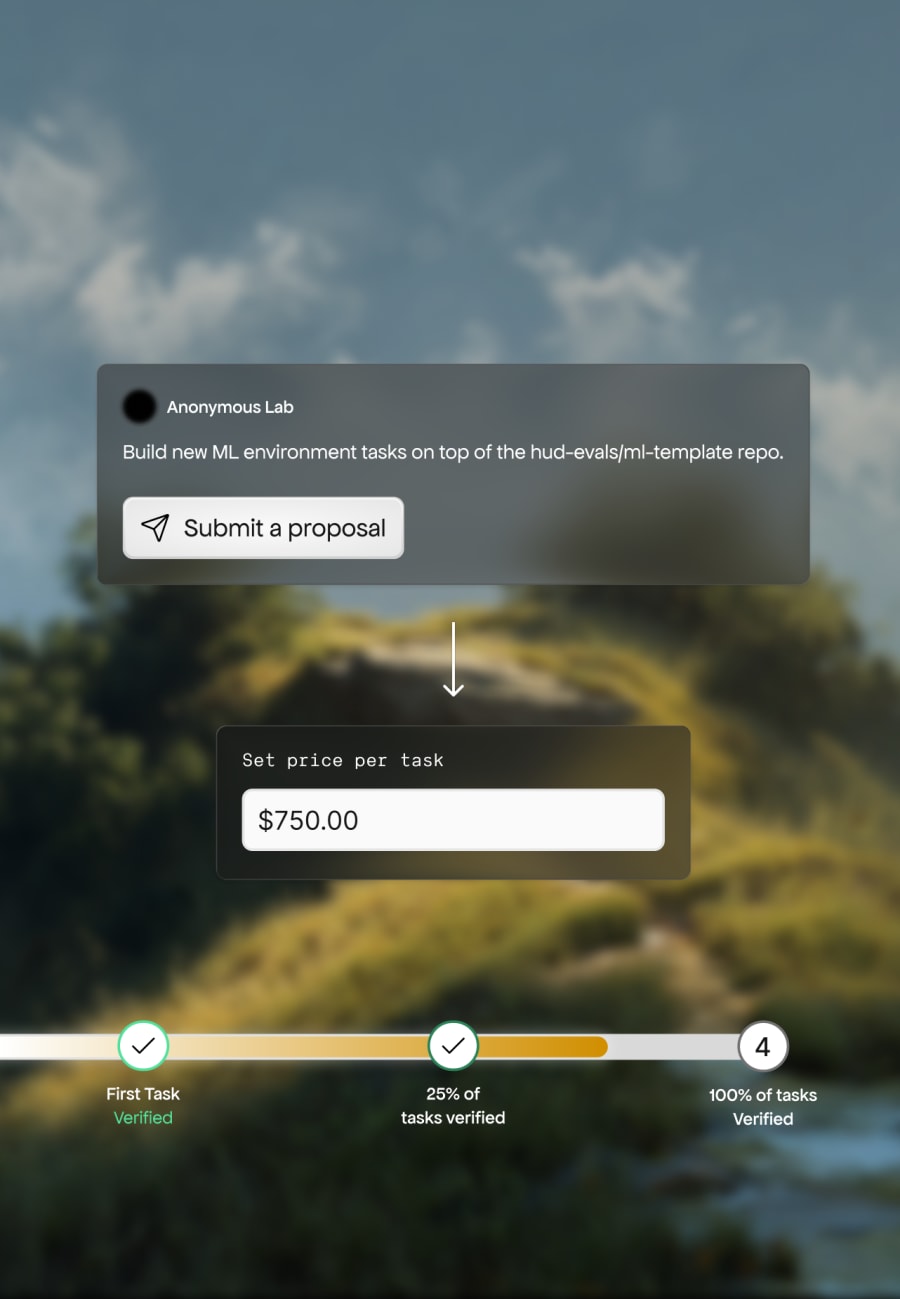
Turn environments into revenue
Sell to research teams on HUD vendor marketplace.
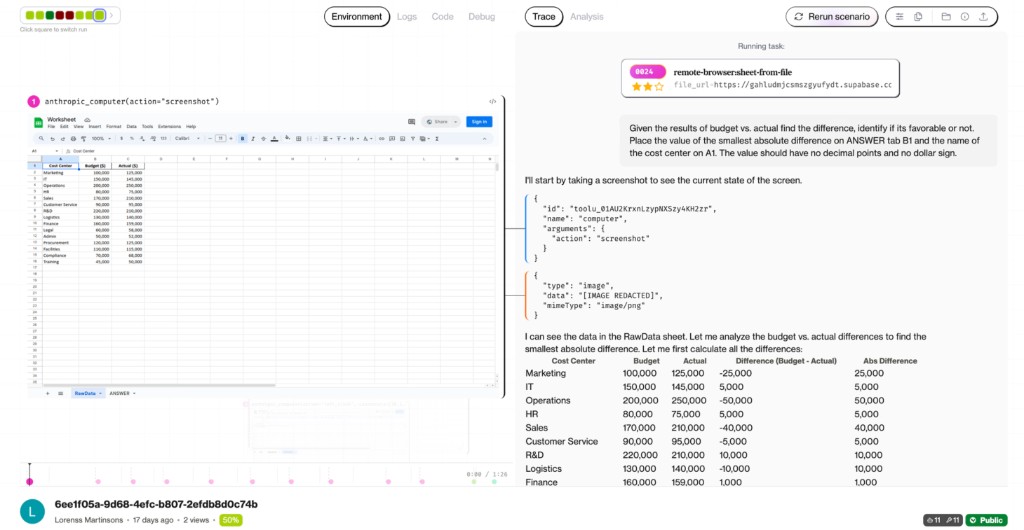
Investigate your environments
Debug agent behavior and improve reward signal by understanding what's actually happening.
QA your tasks automatically
Our agents audit every trace for grader mistakes and reward hacking before they corrupt your tasks.
False Positive Detector
Spots passes that aren't really passes — the agent got credit without genuinely completing the task.
False Positive Detector
Spots passes that aren't really passes — the agent got credit without genuinely completing the task.
Reward Hacking Detector
Flags traces where the agent gamed the eval — test manipulation, output hardcoding, scorer exploits.
Reward Hacking Detector
Flags traces where the agent gamed the eval — test manipulation, output hardcoding, scorer exploits.
Failure Analysis
Surfaces every problem behind a failed run with evidence and a code-level root cause — not just a one-line label.
Failure Analysis
Surfaces every problem behind a failed run with evidence and a code-level root cause — not just a one-line label.
Prompt-Grader Alignment
Verifies the grader's checks line up with what the prompt actually asks for, so evals judge the right behaviors.
Prompt-Grader Alignment
Verifies the grader's checks line up with what the prompt actually asks for, so evals judge the right behaviors.
False Negative Detector
Catches unjustified failures — the agent actually solved the task, but the grader scored it wrong.
False Negative Detector
Catches unjustified failures — the agent actually solved the task, but the grader scored it wrong.
Customer stories
How Sharpe scales high-quality RL environments
Sharpe designs RL environments for coding, AI training, and ML project management using HUD, with full QA on every task they make to ensure the highest quality training data.
How UiPath benchmarks enterprise agents against every frontier model
UiPath brought its UI-CUBE enterprise computer-use benchmark onto HUD, where its own agents and every frontier model are measured against the same enterprise workflows.
Pricing
SDK + Platform Access
Free
- Turn any software into agent tools
- Define templates for evaluations
- Compatible with any agent framework
Cloud
$0.10 / environment hour
- 100+ parallel environment instances
- Live telemetry and debugging
- Detailed trace analysis
Enterprise
Custom pricing
- Train agents on your environments
- Extended 24-hour environment runtime
- SOC 2 compliant infrastructure
- Volume pricing and dedicated support
Are you a student or researcher? Get $100 in free credits with a .edu email. Apply for a grant →